A month ago, I was genuinely excited about this. I took a photo of a pH meter with my phone, gave the image to ChatGPT and asked: “How do I use this?” The AI identified the device, explained the buttons and showed me how to use it. Pretty impressive, right? At the time, I wrote about it as an example of how far the practical use of AI had already come.
Now, about a month later, it already feels old-fashioned.
Not because image recognition or creating instructions for using a device has become useless. But because I have already moved three steps beyond that myself. First, I asked AI for advice and did the work myself. Next, I asked AI to build a complete program for me. Now I give it the entire task.
And this is where things become genuinely interesting.
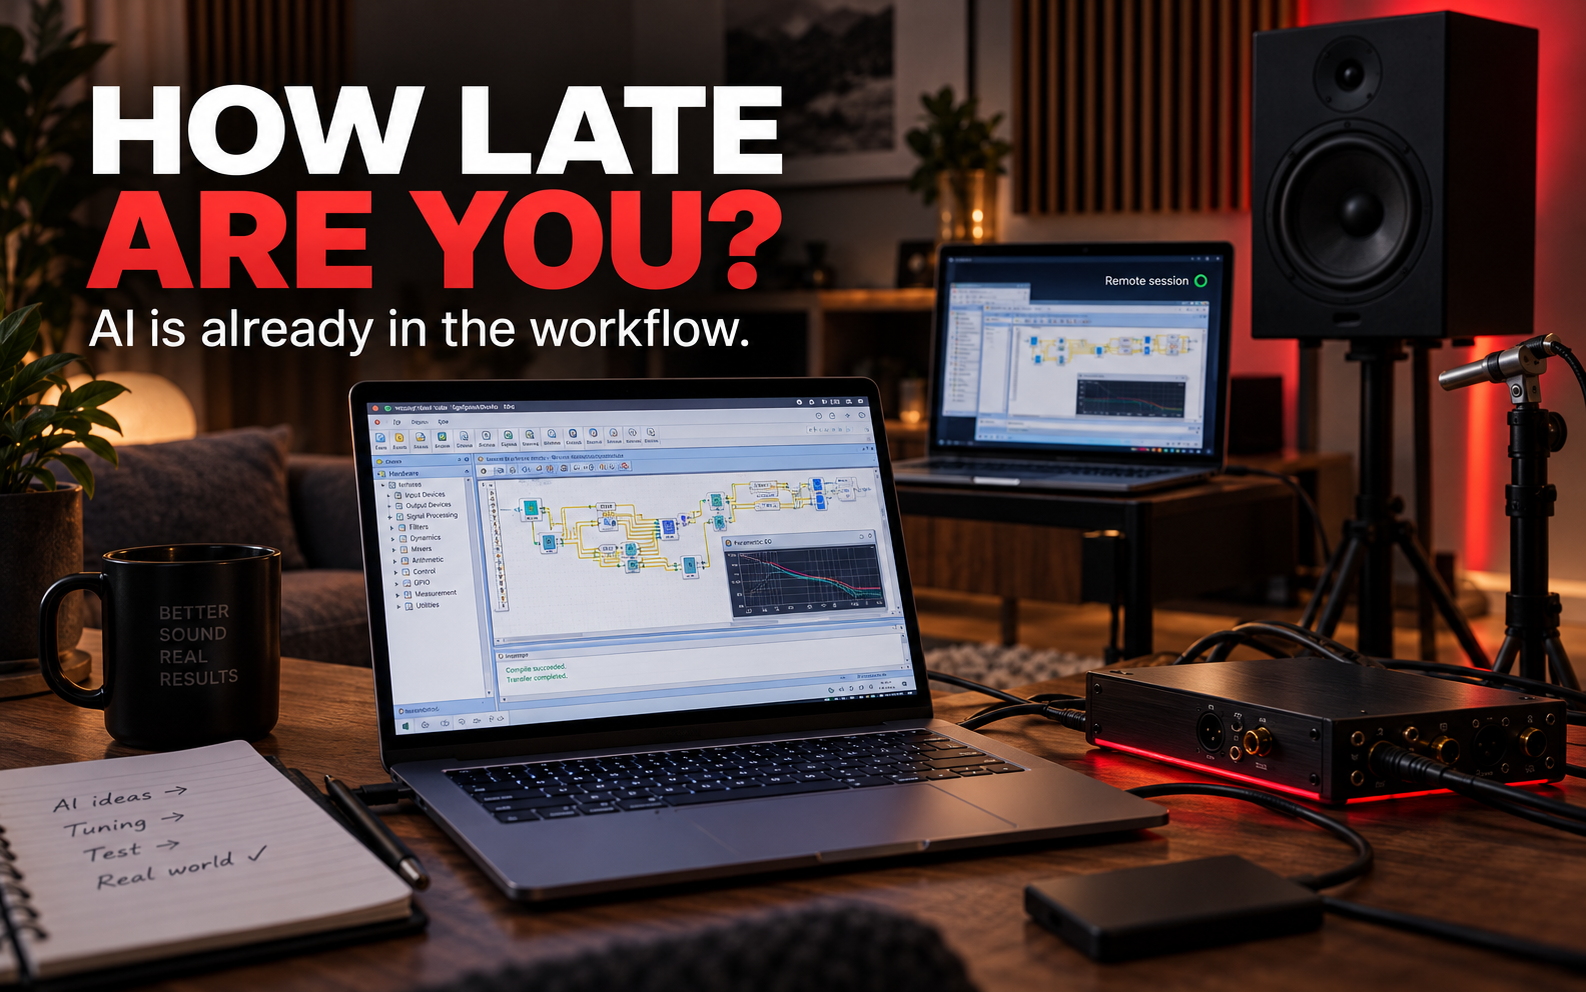
My living room currently contains a small hi-fi studio
I build hi-fi equipment in my spare time, and right now I am working on a pair of three-way active dipole speakers. A speaker is standing in the middle of the living room, surrounded by a measurement microphone, amplifiers, cables and a DSP box that handles the crossovers, delays, corrections and other signal processing between the drivers. The DSP is programmed with SigmaStudio.
There is just one small practical problem. I use a Mac, but SigmaStudio only runs on Windows. I solved this by digging out an old Intel MacBook Air, installing Windows on it and physically connecting it to the DSP hardware. My new Mac, in turn, controls that Windows machine lying on the floor through a remote connection.
Up to this point, this is still perfectly normal geeky hobby stuff.
Then ChatGPT Work and Codex entered the picture.
Three steps in just a few months
The first way I used AI was the familiar one: I asked, it answered, and I did the work. If something did not work, I took a photo, asked again and tried the next option. Even this accelerated the work enormously.
At the next stage, I asked myself a fairly simple question: why should I ask AI to tell me how to build the program? Why not ask it to build the program? I define the architecture, crossover frequencies, filters, PEQs, gains and the other functionality I want. The AI builds the whole thing and gives me a finished program.
For a while, even that felt quite advanced.
Then I realised that even there, I was still an unnecessary middleman.
Give it the objective. Not the task step.
This is the point where my own understanding of AI changed the most.
Work no longer just sits somewhere in the cloud telling me what I should do. It can work on my computer. That alone is a huge leap: AI no longer merely advises a human on how to use a computer. It can physically perform the actual work on the computer itself.
But in my case, the chain goes even further. Work operates on my Mac and uses the remote connection built into it to control another computer lying on my living-room floor. On the Windows machine, it uses SigmaStudio, builds the DSP program, makes changes and tests them. And the chain does not even end at that computer: at the other end of a USB cable sits a physical DSP box.
In practice, Codex is already inside my stereo system.
It builds the program, loads it onto the DSP, reads any errors, fixes them, writes a new version and tests again. I can sit beside it and watch the screen change as the work progresses.
AI is no longer, for me, a black box running somewhere in the cloud that I type questions to in a browser text field. It is on my Mac. It uses the Windows computer on my floor. It communicates with SigmaStudio. And at the end of the chain, it programs physical electronics through which my living-room speakers operate.
AI is no longer only online. It has entered the living room.
And to me, this is a far bigger change than a new chatbot version or a slightly better text generator.
At the same time, companies are still wondering whether they should try ChatGPT
My rough estimate is that around 80% of business decision-makers still have not properly understood what has happened during the past year. And an even smaller share understand how dramatically the pace of development has accelerated in just the last few months.
In the business world, people are still discussing whether documents may be given to ChatGPT. Should employees receive prompt training? Could it perhaps help write emails a little faster? Should we now create an AI policy and establish a working group to investigate the matter?
Meanwhile, I am sitting in my living room on a Sunday watching AI use two computers, build software, communicate with a physical DSP device and take the entire task towards a finished result.
That is quite a gap.
Dinosaurs in the business world have one defining characteristic: they call slowness deliberation.
And if someone is offended by the word dinosaur, I think that is beside the point in this discussion. Technology is not going to slow down while everyone waits to feel comfortable.
“Let’s wait six months” may not mean six months
At least to my eyes, AI development does not currently look linear. New capabilities are built on top of previous ones, combined with each other, and suddenly something that felt advanced a month ago looks primitive today.
A month ago, I took a photo of a device and asked AI how to use it.
Now I give AI the objective, and it goes to the device itself.
If development continues in the same direction, “let’s wait a few more months” does not necessarily mean that you are only a few months behind. In terms of working methods, the gap can grow into years during that time. That is why I sometimes deliberately exaggerate by saying that some companies are already a couple of years late — and soon it will be ten.
Not on the calendar.
In capability.
This is not really an article about DSP
The DSP just happened to be the test subject this time.
The much more interesting question is what this means for companies. For a long time, we have asked: “How could AI help with this task step?” I think that question is already too small.
A better question is: “Why is a human still doing this task step at all?”
And then comes an even more interesting question:
Why give AI a task step when we can give it the objective?
At that point, we are no longer talking about using ChatGPT. We are talking about processes, organisations, leadership, productivity and competitiveness. We are talking about which parts of the work should be done by people and which can be assigned to a system capable of planning, executing, reviewing and correcting its own work.
This is what I believe companies should be discussing right now. Not next year. Not when AI is “ready”.
It will never be ready.
Tomorrow, it will be able to do more again.
The future is not coming. Right now, it is running on a Windows computer on my living-room floor.
And soon, even that will already be old-fashioned.
CRM is one of the most important tools in business and sales. A brand-new tiny company needs one just as much as an old, large one. But what kind of CRM is best for a new company or a first-time entrepreneur?
There are CRM systems coming out of your ears: free and expensive, huge and tiny, and every flavour in between.
But especially for a small, entrepreneur-led company, what is the best CRM?
The one that actually gets used.
One that is easy, clear and fit for purpose.
No extra bells, whistles or other pointless fluff. The harder it is to use, the less it gets used.
The most important thing when choosing a CRM is to stop choosing a CRM. At least for starters. Turn the whole thing around: first analyse what I actually need the CRM for. What do I want to put in it? What do I want to see when I open it? In what format? Which data?
There is your CRM skeleton – and absolutely nothing else. Every extra gizmo bolted around it is pointless: it slows things down, gets in the way and ultimately makes people use the CRM less.
Many off-the-shelf CRMs try to be as versatile as possible, cover every imaginable need and provide a growth platform – for absolutely everything? That is why adopting almost any CRM package usually begins with two steps:
1. Strip away everything extra and unnecessary.
2. Adapt ourselves to the way the remaining skeleton works.
Both are daft. Especially number two: while the basic idea is the same in every CRM, each one still works slightly differently. A small entrepreneur-led company usually has a very strong way of working of its own: what I sell, how I sell it and how I want to track it. It works. So why should it be forced into some CRM process diagram carved in stone?
Why not simply build the CRM around the company’s own process – the one that already works best?
It´s doable.
I analysed the options and ended up with three different models:
1. A completely ready-made CRM, such as HubSpot or Pipedrive. Remove 70% and adapt our own way of working to whatever remains.
2. Build our own from scratch with Codex?
3. Hybrid model: choose an existing platform that is flexible enough, then use the working technology underneath to build our own CRM “from scratch” on top – containing only the functions I will actually use.
I went with option 3, and Airtable got the job. It is a browser-based cloud service: essentially an interface built on top of Excel-style tables, which can be used to generate different CRM systems – or pretty much any other tracking tool. Under the Sales/Marketing section, I found several ready-made CRM templates, each with a slightly different flavour.
And then I found the awe-inspiring button: “Create new +“. Click it and – surprise – a blank canvas opens. Then you start slapping this and that onto it with a very large paintbrush.
There is, however, an easier way: use AI and ChatGPT’s capabilities:
– Create a project in the Work environment
– Tell it which features I want in the CRM and which I do not (a precise list = a better result!)
– Ask the Terra or Sol engine to produce a plan based on my requirements
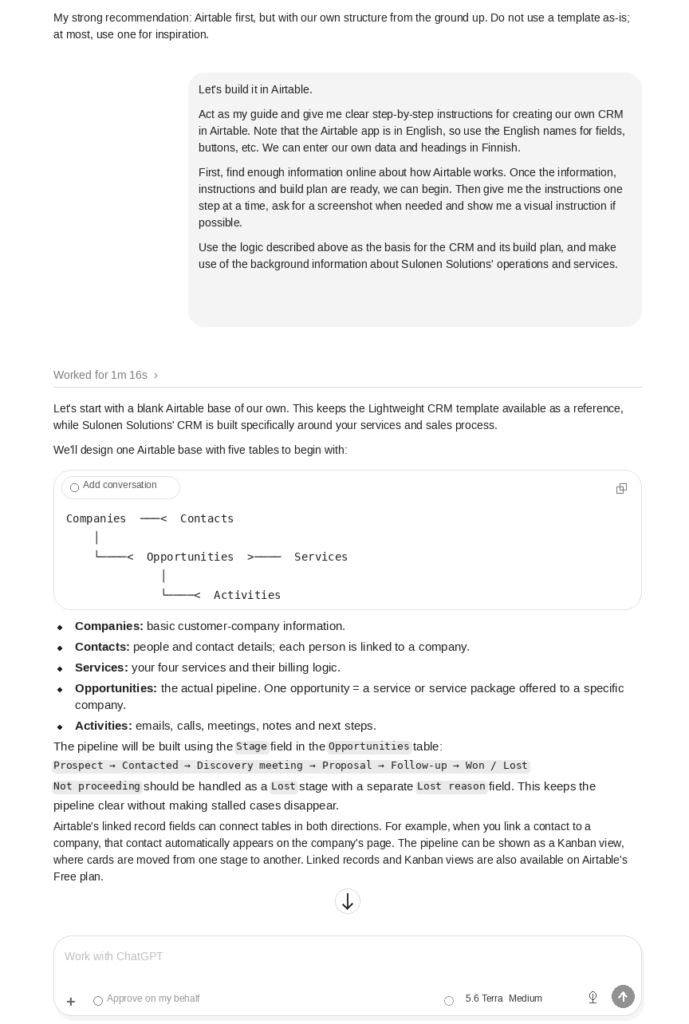
– Once I have approved the plan, ask the AI to guide me step by step through building the new CRM on Airtable
That is what this story is about.
We started after morning coffee, at around nine, like this:
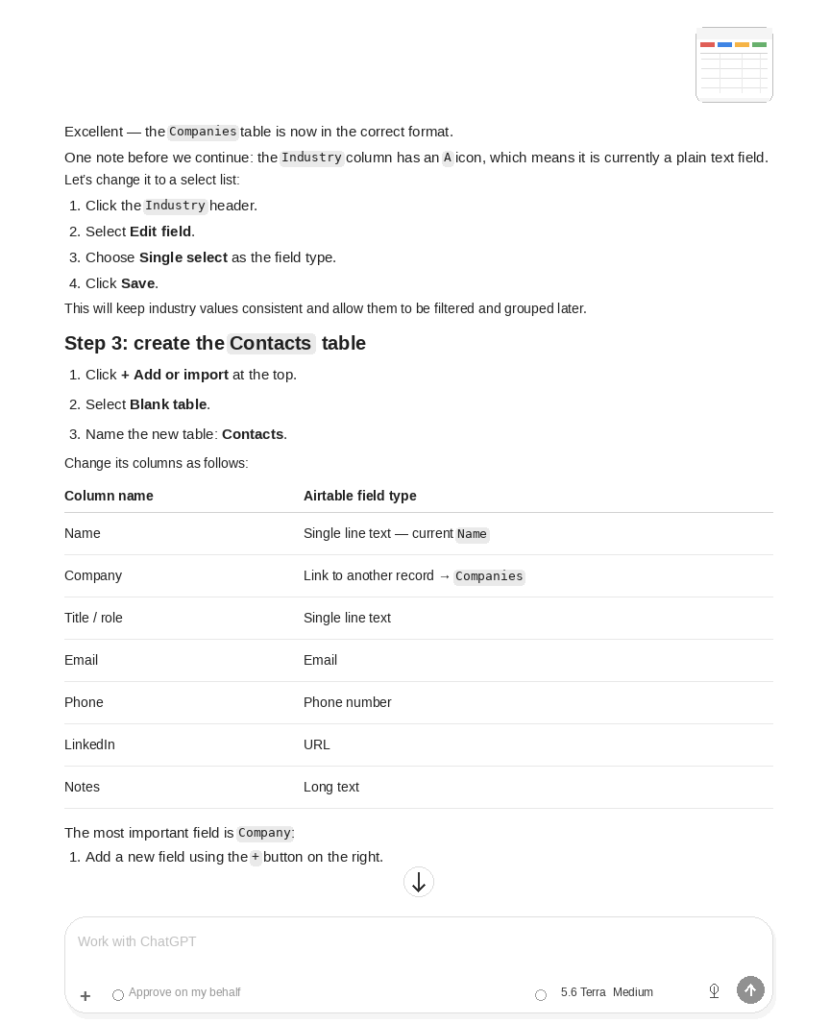
I tend to use screenshots in these projects -> ChatGPT can see what I have done on my screen and guide me when needed, as in the next example:
By 2:30 p.m., it was done. I also told ChatGPT to create a user guide for the CRM, lay it out on Sulonen Solutions’ official Word template, and save it in a specific folder on my Mac.
In between, I had already managed to go cycling, visit the library and stop at the supermarket on the way. Now it is done.
From chat on your phone to the Work workspace, from Luna to Sol, and from everyday questions to complete AI workflows.
Sulonen Solutions | 1 August 2026 | An up-to-date overview
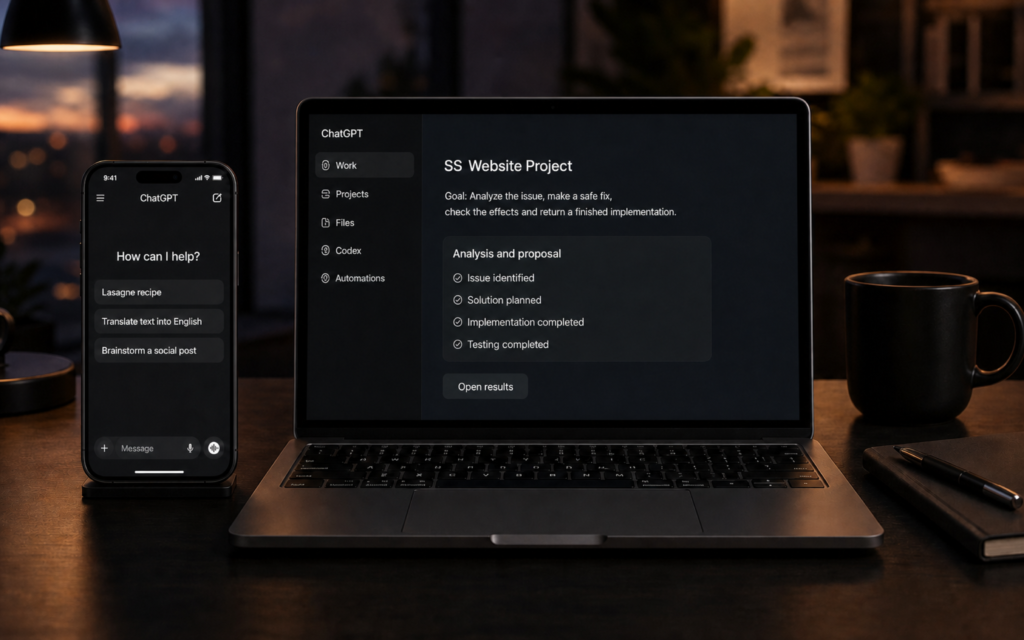
The ChatGPT mobile app and the desktop app for Mac.
I opened the same ChatGPT in two places – and got two very different machines
I opened ChatGPT on my phone. The screen showed the familiar blank conversation and one simple question: “How can I help?”
I opened the same service on my Mac in the desktop app (a local app, not through a browser). I was met by Chat, Work, Projects, Files, Codex, Automations, local folders, tools and several different engines. Same logo, same user account – but a desktop of an entirely different scale. And most importantly: the desktop app can be given access to folders on your computer. It can read material from your machine, produce finished documents, presentations and PDFs – and save them directly to the folder you want.
So was one the ordinary ChatGPT and the other an entirely different product?
No. And yes.
ChatGPT is no longer a single chat window. It is a family of tools that brings conversation, project context, files, web search, agent work, automation and software development together under the same name. In the current offering, OpenAI itself distinguishes three main experiences: Chat for questions and discussion, Work for research and producing finished deliverables, and Codex for software development. [1]
It is worth understanding this distinction before comparing models, tokens or credits. Otherwise, it is easy to try to solve the wrong problem with a tool – and then wonder why the work was slow, expensive or confusing.
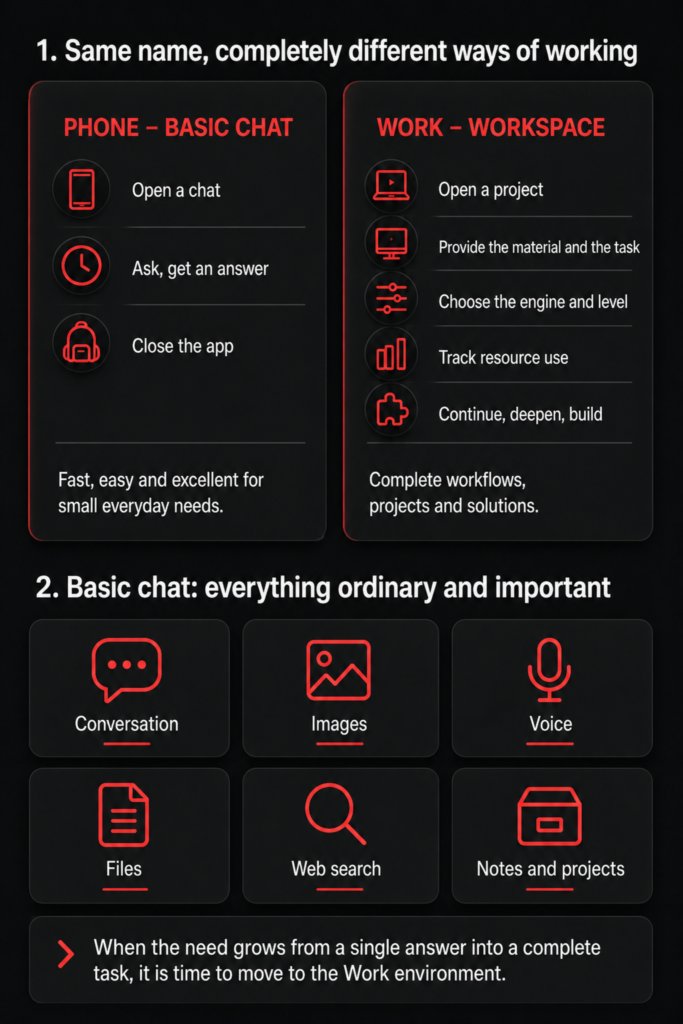
1. Basic Chat has not gone anywhere
Ordinary Chat is still the familiar ChatGPT. You ask it questions, think with it, show it an image, give it a file and refine text with it round by round.
It is especially well suited to situations in which the work is still about thinking rather than execution:
questions and quick investigations
brainstorming and challenging alternatives
writing and editing texts
interpreting and generating images
web search
voice conversations
defining a task before the actual Work run
Basic Chat is light precisely because the user does not need to turn it into a project. Open a conversation, ask, assess the answer and continue.
Think in Chat. Execute in Work. Develop software in Codex.
The boundaries are not concrete walls. You can write code in Chat and ask a single question in Work. But when the way a tool is used matches the nature of the task, the outcome improves too.
Figure 1. The same ChatGPT name – two different ways of working.
2. Is Chat in the desktop app the same as Chat in the browser?
In practice, yes – but the operating environment is not the same.
Ordinary Chat in the new ChatGPT desktop app is the same Chat experience belonging to the same user account and cloud service. Chat conversations sync between the browser and the desktop app. The desktop app therefore does not contain a separate “second ChatGPT brain” that lives inside your Mac or Windows computer. [1]
The difference comes from the shell, permissions and tools connected around it.
The browser version is an easy general-purpose interface. It works without installation, and you can use Chat, projects and, depending on your account, Work and connected services there. The desktop app brings Chat, Work and a separate Codex view together in one application. In addition, with the user’s permission, Work can handle local files and desktop applications. [1][2]
The desktop app also has a built-in browser for Work and Codex tasks. The user and ChatGPT can view the same page, navigate tabs, download files and wait for the user to sign in to a service. The browser has its own browser session; it does not automatically use the sign-ins or cookies of ordinary Chrome. [3]
So the precise answer is this:
Chat in the desktop app is the same ChatGPT conversation. The desktop app as a whole, however, is a much broader working environment than a browser window.
3. Work is not just a longer ordinary chat
In ordinary Chat, I often ask for an answer. In Work, I give an objective.
The difference sounds small, but in practice it changes the entire structure of the work.
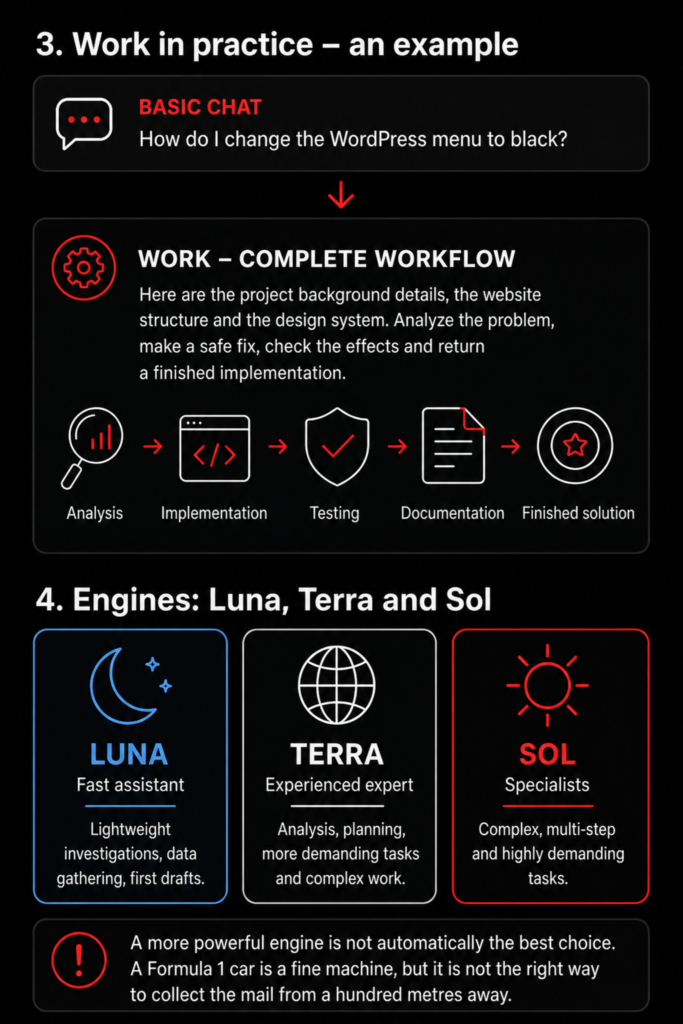
A Chat question could be:
“How do I change a WordPress mobile menu background to black?”
A Work task could be:
“Here are the site structure, the theme in use, the design system and the required files. Identify the structure causing the problem, make the smallest safe change possible, check its effect on desktop and mobile, document the change and return a finished implementation.”
The first asks for instructions. The second gives work.
OpenAI describes Work as an agent that gathers context, plans the approach and works across files, applications and tools to produce finished documents, spreadsheets, presentations, reports and websites. Work conversations done in the cloud can continue between the browser, mobile and desktop app. Local work tasks, in turn, may remain only on that particular computer. [1][4]
Work’s strength is not that it automatically writes a better individual paragraph. Its strength is the workflow:
gathering material
structuring the task
analysis
implementation
review
corrections
documentation
a finished file or other outcome
When a task grows from an individual answer into a complete piece of work, it is time to move to Work.
4. Luna, Terra and Sol are not three reasoning levels
At this point, the interface can easily start to look more like a space programme than a writing assistant.
The engine and the reasoning level are two separate controls.
In the GPT-5.6 family, Luna is the fastest and most affordable model, Terra is the balanced general-purpose model, and Sol is the flagship model for the most demanding tasks. In Work and Codex, Plus, Pro, Business and Enterprise users can, depending on their account and the rollout stage, choose between these three and separately set the reasoning level for the task. In ordinary Chat, Terra and Luna cannot be selected; GPT-5.6 Sol operates behind the reasoning options there, while GPT-5.5 Instant serves as the fast everyday default model. [5][6]
This is why the formula “Luna = fast, Terra = medium and Sol = high” should not be taken literally. It is a useful first rule of thumb, but technically the choice is two-dimensional:
How capable and expensive an engine does the task require?
How much time and computation is it worth using for this particular task?
Sol can be set to do a light run. In some environments, Luna can be given more time to reason. The most powerful combination is not automatically the best combination.
A Formula 1 car is a fine machine. Even so, it is not the right vehicle for fetching the post from a hundred metres away.
Figure 2. A Work task and the practical division of labour among GPT-5.6 engines.
5. What should you actually do with Luna, Terra and Sol?
There is no perfect boundary, because a task’s difficulty is not visible from its length. One short question can contain a difficult contradiction. An inventory of a hundred files, in turn, can be lengthy but mechanical work.
The following is a practical division of labour.
Luna – the fast assistant
Luna is suited to tasks where the structure of the work is clear and the cost of error is low:
file lists and material inventories
classification, extraction and organisation
summarising provided text
format conversion and mechanical cleanup
first drafts
repeated checks for which the rules are precisely defined
Terra – the experienced general-purpose model
Terra is the sensible default for most Work tasks:
analysis of several sources
plans and comparisons
ordinary expert reports
multi-step but scoped implementation
a technical review of a website or document package
building a finished draft from provided material
Sol – special forces
Sol is worth using when the task involves genuinely difficult inference or a high cost of correction:
unclear and contradictory source information
difficult root-cause analysis
a whole spanning several systems or files
technical solutions that change the architecture
a critical final audit
a situation in which the wrong solution creates a great deal of new work
Sol does not remove the need for review. It simply earns its place when a task genuinely needs its persistence and ability to manage complex wholes.
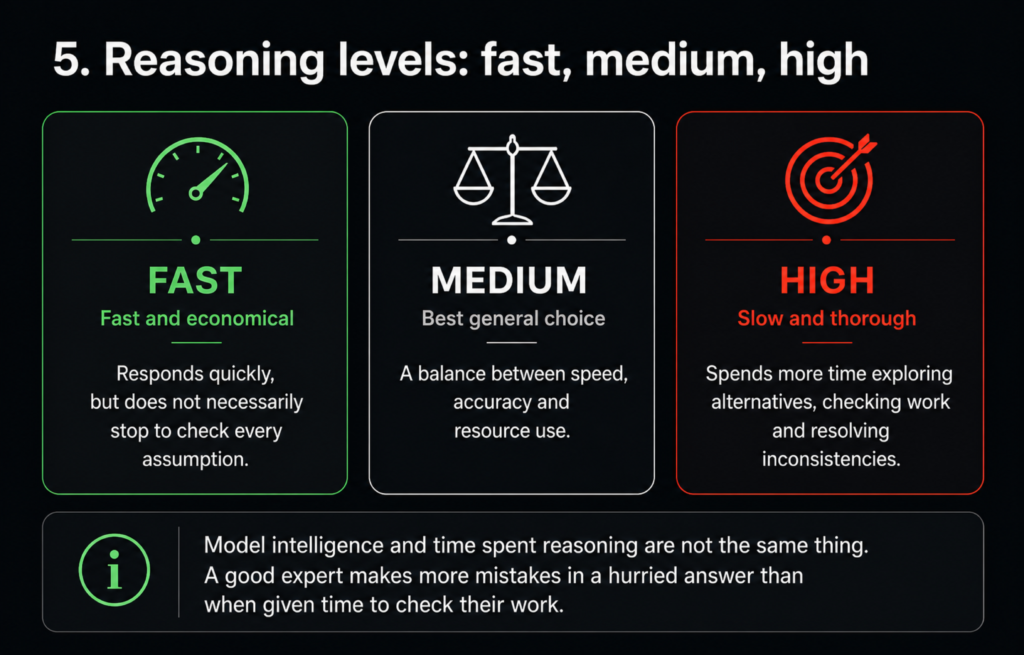
6. Reasoning level indicates time spent working – not intelligence alone
Current ChatGPT distinguishes fast responses and deeper reasoning more visibly than before. In ordinary Chat, the choices appear, for example, as Instant, Medium, High and, on some accounts, Extra High or Pro levels. OpenAI describes Medium as more considered than usual, and High as longer reasoning for complex, multi-step tasks. [7]
A fast level is suitable when the task is clear and the answer is easy to verify.
The medium level is a good default for expert work.
The high level should be reserved for situations where the model needs to:
compare several alternatives
identify contradictions
check its own work
solve a multi-step problem
take many constraints into account simultaneously
High reasoning is not magic dust. A poorly scoped task remains poorly scoped even if it is thought about for three times longer.
Let us take a practical example at this point:
Think of an essay written at comprehensive school. The lightweight Luna engine is like a basic-level essay writer. It will produce something finished, but not necessarily the top result in the class. The Sol engine, by contrast, is the class’s most innovative pupil with a broad knowledge base, who writes a first-rate and insightful essay by combining a great deal of knowledge learned over the year.
The reasoning level (Fast – Medium – Heavy), on the other hand, means the time that the same writer (engine) spends on the work. With fast (but light) reasoning, even the best writer in the class may make mistakes in their essay; some illogicality goes unnoticed, there is a typo somewhere… But the result was finished quickly. The heaviest reasoning model, in turn, means that the writer does not stop when the essay is complete – they read it through, check it again, read it a third time – by this stage a few errors have already been found and corrected. The finished essay is submitted only after it has been read through, corrected and fine-tuned many times.
Every AI engine does this same thing. At the highest reasoning level, AI does not quickly hand in unfinished work. Especially with the SOL model, you can see how it “stress-tests” its answer, turns it every which way, checks, compares, corrects, reads again and checks once more.
A model does not always need more time. First, it needs a better task.
Figure 3. The model and the reasoning level are two separate choices.
7. What consumes tokens – and what does not?
A token is a technical unit for processing text. A word can consist of one or more tokens, and punctuation, spaces and parts of words also affect the count. The model processes input tokens and produces its answer as new tokens. Some reasoning models also involve internal reasoning tokens. [8]
Tokens are used when the model processes content:
the request you write
relevant conversation history brought into the task
project instructions and other context
file content given for the model to read
text retrieved from a browser or connected services
the answer produced by the model
internal reasoning in some models
Simply opening the application, reading an old answer or browsing the conversation history is not a new model run. When you ask the model to read, assess, search for or produce something, resources begin to be used.
Images, audio, computer use and other tools also do not always turn directly into ordinary text tokens. They may have their own usage meters, tool calls or consumption that affects the shared agent allowance.
A long conversation does not automatically mean that the entire chain is billed word for word again on every turn. The system may use retrieval, summarisation and caching. Still, the general rule holds: the more relevant background the model has to read on every turn, the larger the input becomes. In API use, tokens read from cache are cheaper than new input, but they are not the same as zero consumption. [8]
8. Token, usage limit and credit are three different things
These are easily confused because the interface usually shows the user usage limits and credits – not the exact token count for an individual response.
A token is a technical unit of measurement.
A usage limit is the permitted amount of messages, reasoning or agent work included in a subscription during a given period.
A credit is a paid or administrative consumption unit that supports specific features after the subscription’s included usage or in an organisation’s shared consumption model.
A ChatGPT subscription and the OpenAI API are different products. In the API, usage is priced directly on the basis of the tokens processed by the model and tool calls. With an ordinary ChatGPT subscription, the user primarily operates within subscription-specific usage limits.
On Plus and Pro accounts, Codex, Work and, for example, ChatGPT for Excel may, depending on the account and feature rollout, use the same agent-work allowance. When included usage runs out, supported features may use purchased credits. OpenAI stresses that the available options are always shown on the account’s own Usage page, because feature availability changes as rollouts progress. [9]
This leads to a practical guideline:
Do not optimise only the token. Optimise the finished work.
The cheapest model is not cheap if the task has to be done three times. The most expensive model is not efficient if it spends fifteen minutes thinking about something Luna could have organised in two minutes.
9. This is how work should be broken down
A good Work task is not a huge wish. It is a managed work package.
A working rhythm looks like this:
1. Define the objective in Chat
First discuss what is actually being done. Define the outcome, risks, material and acceptance criteria. (This does not usually consume usage limits -> check your own subscription.) I often do the planning for an entire project from start to finish in Chat. We plan, assess, invent and reflect. Only when there is a need to produce a concrete finished document or programme, or to analyse a huge number of files and emails and return a report from them, do we have the Work environment do it, for example with Luna or Terra. I use Chat’s help for this too: I ask it to create a finished “prompt”, in other words a precise instruction for the Work agent. Chat can summarise our discussion up to that point and turn it into a strict instruction for the Work agent, so that it does not start improvising or doing unnecessary work.
2. Keep the material compact
Give Work only the necessary files and permanent project instructions. A hundred-page backstory does not help if the task concerns one CSS setting.
3. Start with an inventory
Luna can inventory the material, identify files and make the first classification. At this stage, do not fix everything yet. If you want to form an overall picture of material containing numerous emails, several folders of files and 30–40 individual documents, it is not worth immediately putting the whole mass through a SOL agent at the highest reasoning level. You can do it, but your Plus subscription’s weekly allowance will be full already… I tell Luna to read it through at the medium or high reasoning level and only produce a list of the materials, not an analysis yet. When you tell Luna this objective right at the start in the prompt, it does not analyse yet but only creates a finished “source list” in a form that Terra can easily continue from. Terra can then directly disregard 70% of the material that is not relevant and analyse only what matters.
4. Execute with Terra
Terra is suited to ordinary analysis, planning and scoped implementation. Ask for one clear delivery: for example, a corrected file, a finished article or a review report. Or ask for an analysis of the entire source material that you just “cleaned up” with Luna – saving tokens.
5. Escalate only the difficult part to Sol
When you encounter a contradiction, an unclear root cause or a broad chain of effects, move that specific problem to Sol. Do not move the whole project automatically. I often use SOL only after I have received a finished analysis, report or material from Terra. At that point, you can do the final stress test with SOL.
6. Separate implementation and review
Finally, request a separate review against the acceptance criteria. In critical work, the reviewer can be a separate run or a more capable model.
7. End the chain in a controlled way
Ask for a short summary: what was done, which files were changed, what remains open and what the next step is. When the objective or component changes, start a new chain. It is also good to switch chains regularly if the conversation has become long and already contains 50–100 questions and answers. If you make Chat “tow along” the context of the whole conversation, it slows down. In that case, ask it to create a “transfer package” and say that you are moving to a new chain. Chat can create, for example, a compact PDF or .md file that you can copy to the new chain and continue where you left off – but without the old burden.
One outcome. One responsibility. One checklist.
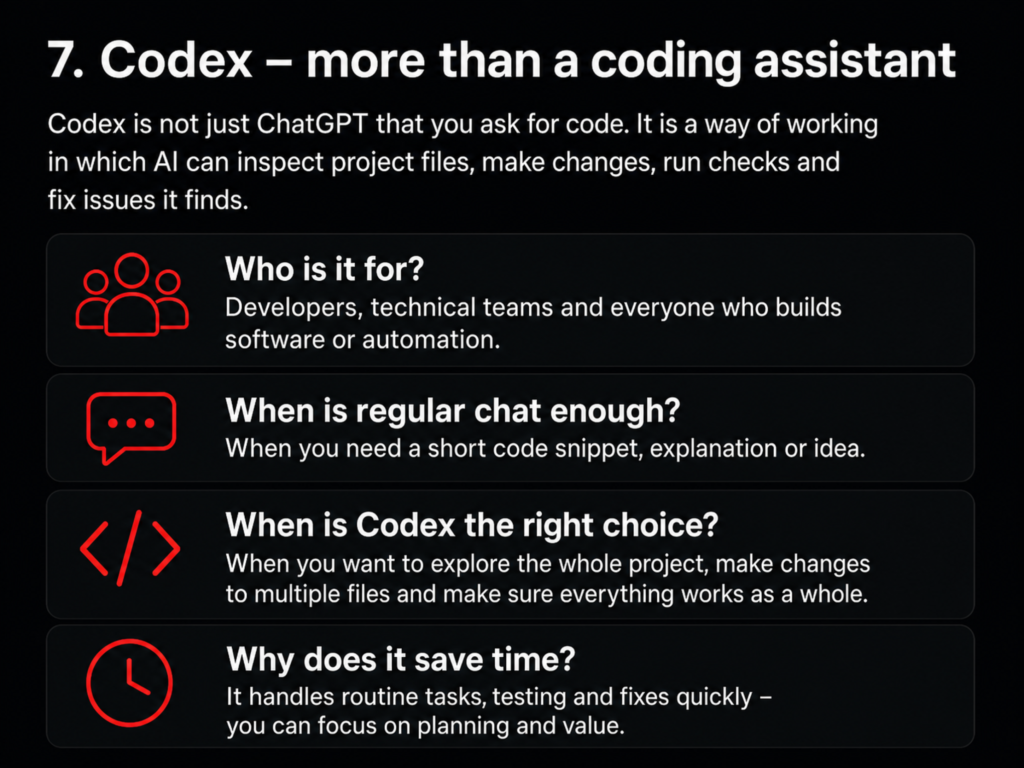
10. Codex is more than a chat that can write code
You can ask Chat for a snippet of code. Codex is used when the code needs to change in a real project.
Codex is a working environment that can use local folders, software repositories, the terminal and developer tools. It can make changes, run tests and commands, inspect differences, and go through the structure of a software project. Its history and work view are separate from ordinary ChatGPT history, and Codex is not selectable as an ordinary web or mobile view. [1][10]
When is ordinary Chat enough?
When you need a short code example, an explanation, an idea or an interpretation of a single error message.
When is Codex the right choice?
When you want to examine an entire project, make changes to several files, run tests, check dependencies and ensure that the whole still works after the change.
Codex saves time because the user does not need to transfer every file, error message and fix manually through a conversation window. It sees the worksite – not just one detached screw.
Figure 4. Codex is a project workspace, not merely a conversation that answers with code.
Summary: the right tool matters more than the biggest model
ChatGPT is not one window. It is a family of tools.
Chat is conversation, thinking and quick help. Work is a goal-oriented workflow that gathers material and produces a finished outcome. Codex is the desktop for software work, where changes can be made, tested and reviewed in a real project.
Luna is suited to light and well-defined tasks. Terra is a strong default for ordinary expert work. Sol is worth using when difficulty, uncertainty or the cost of error genuinely calls for it.
Reasoning level is not the same thing as the model name. A token is not the same thing as a credit. The desktop app is not a different ChatGPT – but it opens a considerably larger toolset for the same ChatGPT.
The best model is not always the most efficient model.
The best model is the lightest model that completes the work reliably.